
link之家
链接快照平台
- 输入网页链接,自动生成快照
- 标签化管理网页链接
相关文章推荐
|
重感情的板凳 · java如何高效的对比数据 ...· 1 年前 · |
|
|
聪明伶俐的冰棍 · 地理位置和经纬度坐标之间如何转换?Pytho ...· 3 年前 · |
|
|
温文尔雅的野马 · 如何在SQL ...· 3 年前 · |

本文内容由阿里云实名注册用户自发贡献,版权归原作者所有,阿里云开发者社区不拥有其著作权,亦不承担相应法律责任。具体规则请查看《
阿里云开发者社区用户服务协议
》和
《
阿里云开发者社区知识产权保护指引
》。如果您发现本社区中有涉嫌抄袭的内容,填写
侵权投诉表单
进行举报,一经查实,本社区将立刻删除涉嫌侵权内容。
一个索引列并不一定是底层表的一个列,也可以是从表的一列或多列计算而来的一个函数或者标量表达式。这种特性对于根据计算结果快速获取表中内容是有用的。
例如,一种进行大小写不敏感比较的常用方法是使用lower函数:
SELECT * FROM test1 WHERE low.
李博 bluemind
前面几节中给出的规则将导致为SQL查询中的所有表达式分配非unknown数据类型, 除非未指定类型文字显示为SELECT命令的简单输出列。例如,在
SELECT 'Hello World';
没有什么可以确定字符串文字应被视为什么类型。
李博 bluemind
开发者学堂课程【 PostgreSQL快速入门 :3 PostgreSQL psql的使用,SQL语法,数据类型,递归SQL用法(二)】学习笔记与课程紧密联系,让用户快速学习知识
课程地址 : https://developer.aliyun.com/learning/course/16/detail/89
3 PostgreSQL psql的使用,SQL语法,数据类型,递归SQL用法(二)
内容介绍 :
三 、PostgreSQL数据库基本操作
四 、PostgreSQL数据类型介绍
三、PostgreSQL数据库基本操作
1、PostgreSQL数据类型介绍
通过当前数据库的from pg _ type ; 可以看到有哪些类型 , 新建的类型也可以看到 , 类型里面有存储 , 存储结构 , p存储在当前的表里面 , 以不压缩的形式存储 , e是存储在外面以不压缩的形式存储 , m是存储在当前表压缩的形式存储 , x存储在post表以压缩的形式存储 。 数据类型
Category
Array types 数组
Boolean types Boolean 逻辑
Composite types 复合类型
Date/time types 时间类型或者日期类型
Enum types 枚举类型
Geometric types 几何类型
Network address types 网络类型
Numeric types 数字类型
Pseudo-types 虚拟类型
String types String 类型
Timespan types 时间块类型包括因特网
User-defined types 用户定义类型
Bit-string types Bit-string 类型
unknown type 未知类型
2、 表的操作(创建,插入,更新,删除,截断,删除,重命名,修改表的属性..)
四、PostgreSQL数据类型介绍
1、 常用数据类型 , 数字
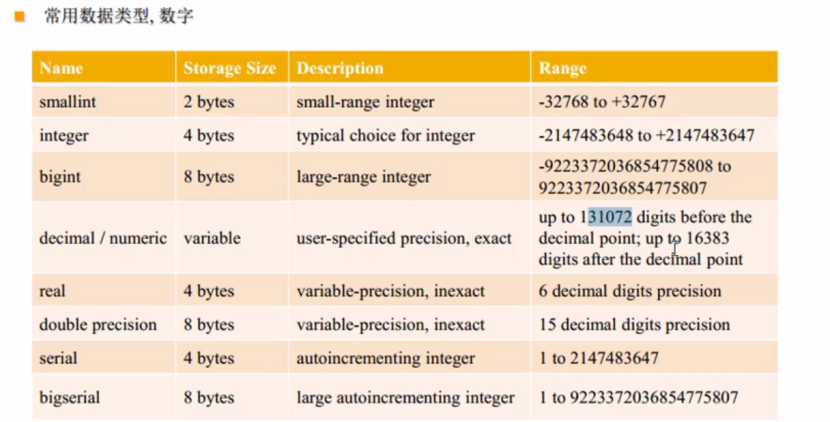
Smallint , 2 bytes 固定存储 2 个字节 , -32768 to +32767 范围
Integer , 4 bytes 四个字节 , Bigint , 8 bytes 八个字节 。
Real , variable-precision, inexact 不精确的类型 , double precision , 15 decimal digits precision 最多存储 15 个有意义的数字 。
not null default nextval('t_ id _ seq' : :regclass )自动创建序列
序列的起始值是 1, bigint 类型最大值9223372036854725807 , 不允许循环 , 创建serial自动创建序列并且把默认的值赋予给下一个序列的值 。
create table t1<id seria18>;
2、常用数据类型,字符
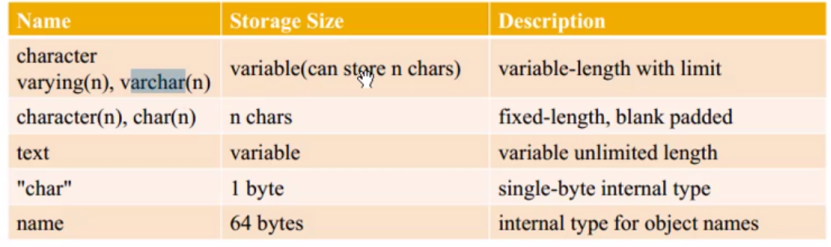
variable( can store n chars) 字符的长度而不是字节 , 存储的最多是一个字符 , 不是一个字节 。
ixed-length, blank padded 固定长度 , 如果没有达到这个长度会以空格填充的固定的字符串类型 。
variable unlimited length 不指定长度 , 无限长度的 variable 类型 , 最大支持 1 gb的存储空间 。
single-byte internal type 单字节使用的类型 。
后面两个是字节 , 前面是字符 , char 20 是存 20 个字符而不是 20 个字节 。
存中文字
Inscrt into t2 vaLues <’ 你好呀a ’>;
存的是字符 , 中文字占了很多个字符 , 或者更多的字节
insert into t2 values < ' abc' > ;
select pg. column size(c1) , c1 from t2;
你好呀占 10 个字节 , abc只占了 4 个字节 , 是字符个数 , 而不是字节数 。
3、 常用数据类型 , 时间

timestamp [(p)]without time zone] , both date and time (no time zone) 带日期和时间 , 不带时区 。
timestamp [ (p) ] withtime zone , both date and time, with time zone 带日期时间时区 。
timestamp [ (p) ] withtime zone , both date and time, with time zone 带日期时间时区 , 1microsecond 114 digits 精度可以到达十四分之一微秒的结果 。
Date , date (no time of day) 只有日期 , time [ (p) ][ without
time zone] , time of day (no date) 只有时间 。
interval [ fields][(p)] , time interval 时间间隔 , 一年两年一小时都是间隔 , 组合很多 。
特殊日期/时间输入
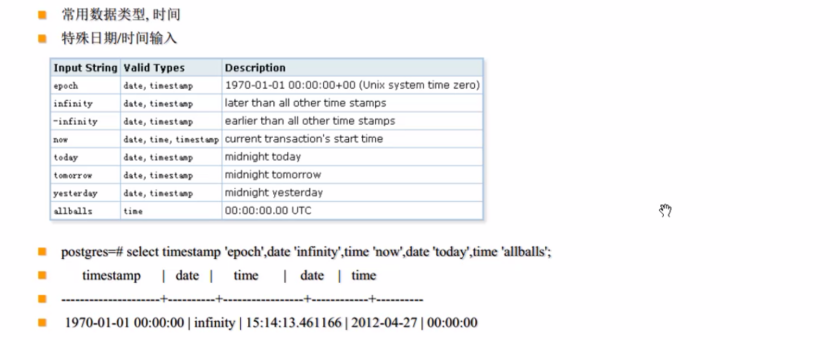
infinity 大于所有指定的时间 , 指定时间两万年 , 不管执行多少都大 ,
-infinity 不管执行多少都大 , now 当前时间 , today 当前日期的零点 , tomorrom 明天 , yesterday 昨天 , allballs 所有的字段都是 0 。
postgres= =# select timestamp 'epoch'
,
date 'infinity'
,
time 'now
,
date 'today'
,
time 'allballs';
Timestamp
Date
time
date
time
1970-01-01 00:00:00
infinity
15:14:13.461166 2012-04-27 00:00:00
时间输入输出格式
|
Style Specification |
De scription |
Example |
||
|
ISO |
ISO 8601/SQL standard |
1997-12-1707:37:16-08 |
||
|
SQL |
traditional style |
12/17/1997 07:37:16.00 PST |
||
|
POSTGRES |
original style |
Wed Dec 17 07:37:16 1997 PST |
||
|
German |
regional style |
17.12.1997 07:37:16,00 PST |
||
|
datestyle Setting |
Input Ordering |
Example Output |
||
|
SQL, DMY 指定设置 , 输出的顺序 |
dlay'month/year |
17/12/199715:37:16.00 CET |
||
|
SQL, MDY |
mon th/ dlay/year |
12/17/199707:37:16.00 PST |
||
|
Postges, day |
day'month/year |
Wed 17 Dec 07:37:16 1997 PST |
||
postgres= =# set datestyle ='SQL
,
DMY";
postgres= =# select now
()
;
27/04/2012 15:49:51 373789 CST
postgres= =# set datestyle= ='SQL
,
MDY';
postgres =# select now
()
;
04/27/2012 l5:50:07 882063 CST
时间间隔i m terval格式
|
Abbreviation |
Meaning |
|
Y |
Years |
|
M |
Months (in the date part) |
|
W |
Weeks |
|
D |
Days |
|
H |
Hours |
|
M |
Minutes (in the time part) |
|
s |
Seconds |
[@] quantity unit [quantity unit...] [direction]
P quantity unit [ quantity unit ..] [ T [ quantity unit ..]
P [ years-months-days ] [ T hours:minutes:seconds ]
IntervalStyle样式
|
Style Specificatior |
Year-Month Interval |
Day-Time Interval |
Mixed Interval |
|
sql_ standard |
1-2 |
34:05:06 |
-1-2 +3 -4:05:06 |
|
post gre s |
1 year 2 mons |
3 days 04:05:06 |
-1 year -2 mons +3 days -04:05:06 |
|
post gre sverbose |
@1 year 2 mons |
@3days4hours5mins6secs |
@1year2mons-3days 4 hours5 minsб secs ago |
|
iso_8601 |
P1Y2M |
P3DT4H5M6S |
P-1Y-2M3DT-4H-5M-6S |
postgres =# snow mtervarstyie ;
postgres
postgres- =# select interval 'P-1Y-2M3DT-4H-5M-6S";
-1 years -2 mons +3 days -04:05:06
指定一年两个月三日小时分秒时间间隔类型
select now()- current_ date ;
22
:
21
:
01
.
361042
select now()- current_ date
;当前时间
,
当前日期
22
:
21
:
09
.
004178
postgres =#select interval'l day ago';
-
1
days
postgres =# set IntervalStyle ='sql_ standard';
postgres= =# select interval 'P-1Y-2M3DT 4H-5M-6S';
-1-2 +3 -4:05:06
4、 常用数据类型 , 布尔逻辑
|
Name |
Storage Size |
Description |
|
boolean |
1 byte |
state of true or false |
真
TRUE 't' 'true' 'y' 'yes' 'on' ' 1 '
假
FALSE 'f' 'false' 'n' 'no' 'off'0'
unknown (三价逻辑运算)
NULL
htt://blog. 1 63. , com/digoal@ 1 26/blog/static/1638770402013024224461751 /
|
A AND B |
TRUE |
UNKNOWN |
FALSE |
|
TRUE |
TRUE |
UNKNOWN |
FALSE |
|
UNKNOWN |
UNKNOWN |
UNKNOWN |
FALSE |
|
FALSE |
FALSE |
FALSE |
FALSE |
|
A OR B |
TRUE |
UNKNOWN |
FALSE |
|
TRUE |
TRUE |
TRUE |
TRUE |
|
UNKNOWN |
TRUE |
UNKNOWN |
UNKNOWN |
|
FALSE |
TRUE |
UNKNOWN |
FALSE |
|
A |
NOT A |
|
TRUE |
False |
|
Unknown |
Unknown |
|
False |
True |
5、常用数据类型,枚举
创建自定义类型 , 只存储三个字段 , 三个词 , 除此之外存值就会报错
CREATE TYPE mood AS ENUM ('sad, 'ok', "happy);
CREATE TABLE person (name text,current mood mood);
INSERT INTO person VALUES ("Moe', "happy');
SELECT * FROM person WHERE current mood = "happy';
Name current mood
Moe happy
(1 row)
输入一个不存在的枚举值,将报错
postgres= # SELECT * FROM person WHERE current _mood = "happ';
ERROR: invalid input value for enum mood: "happ
"
报不存在的错误
,
无效值
避免报错的方法,把枚举转换成text
postgres =# SELECT * FROM person WHERE current mood:text = "happ';
Name current mood
(0 rows)
枚举值每一个在行中占用4 bytes :
postgres= =# select current_ mood,pg_ column_ size(current_ mood) from person;
current_ mood|pg _ecolumn _size
Happy |4
枚举的标签在定义中最大限制由NAMEDATALEN决定,默认是64-1,前面已经讲过。 创建一个表 , 表名是 NAME 类型 , 也是由 NAMEDATALEN 决定 。 最多能存储 63 个字符
查找枚举的数据结构 :
postgres=# select oid,typname from pg_ type where typname ='mood'; 枚举值不能超过 63 字符
Oid|typname
3952969|mood
postgres =# select * from pg_enum where enumtypid= 3952969; 通过 pg_enum 查询值 , enumlabel标签也是name类型
Enumtypid|enumsortorder|enumlabel
3952969 1 Isad
3952969 2 ok
3952969 3 happy
枚举类型变更, 可以往里面添加某一个值 , 添加在某一个值的前面 , 或者添加在某一个值的后面 , 但是正常是往后添加 , 让性能更好 ,
ALTER TYPE name ADD VALUE new_ enum_ value [ { BEFORE | AFTER } existing_ enum_ value ]
This form adds a new value to an enum type. If the new value's place in the enum's ordering is not specified using BEFORE or AFTER, then the
new item is placed at the end of the list of values.
注意事项,添加枚举元素时尽量不要改动原来的元素的位置,即尽量新增值插到最后。
否则可能会带来性能问题。
ALTER TYPE .. ADD VALUE (the form that adds a new value to an enum type) cannot be executed inside a transaction block.
Comparisons involving an added enum value will sometimes be slower than comparisons involving only original members of the enum type. This
will usually only occur if BEFORE or AFTER is used to set the new value's sort position somewhere other than at the end of the list. However,
sometimes it will happen even though the new value is added at the end (this occurs if the OID counter "wrapped around" since the original creation
of the enum type). The slowdown is usually insignifcant; but if it matters, optimal performance can be regained by dropping and recreating the
enum type, or by dumping and reloading the database.
6、money类型
显示和客户端参数lc_ monetary有关
|
Name |
Storage Size |
Description |
Range |
|
money |
8 bytes |
currency amount |
-92233720368547758.08 to +92233720368547758.07 |
postgres -# show le_ monetary;
C
postgres= # SELECT 712.345'::money;
$12.35
postgres= =# set le_ monetary='zh_ CN";
postgres= # SELECT '12.34S'::money;
¥12.35
人民币换算成美元
,
只是进行货币符号
。
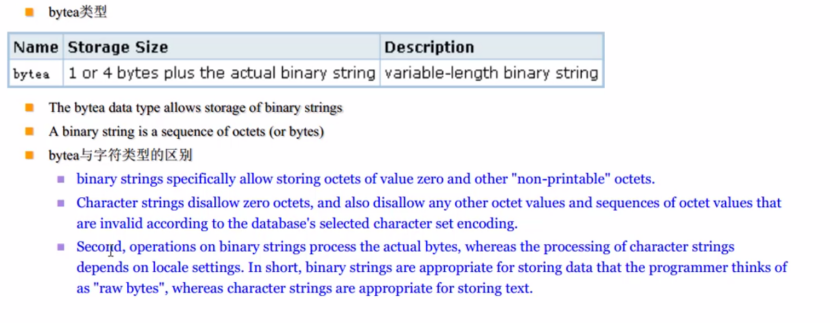
7、bytea 类型
存储的是一个一个的字节流 , 比如存在字符串类型里面 , 会报错的情况下可以选择bytea类型 , 什么字符都可以存 , 允许存空字符 。
同时支持两种格式输入
escape
select E\3361\255\276\357*:bytea;
hex, 每两个16进制数字为一组,表示一个"raw byte"
SELECT E'\x DE AD BE EF:':bytea;
支持两种格式输出,需配置
9.0引入hex输出(通过配置bytea_ _output)
9.0以前为escape输出
如果有从老版本数据库迁移到9.0及以后版本的情况,需要注意,可能再次与程序不兼容,只需要将默认值调整为escape即可。
推荐使用hex格式输入输出 。
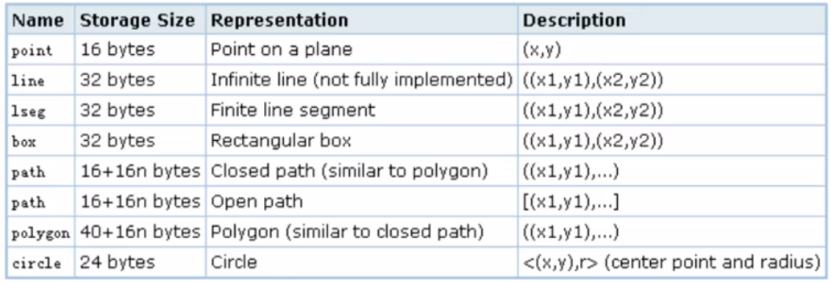
8、 几何类型
存储点 , 存储线 , 存储线段 , 存储盒子 , 存储矩阵 , 存储路径 , 路径可以是一条闭环 , 可以是一条打开的环 , 存储任意一个几何类型 , 几何类型类似于任意一个闭环路径 , 存储一个圆 。
9、 网络地址类型
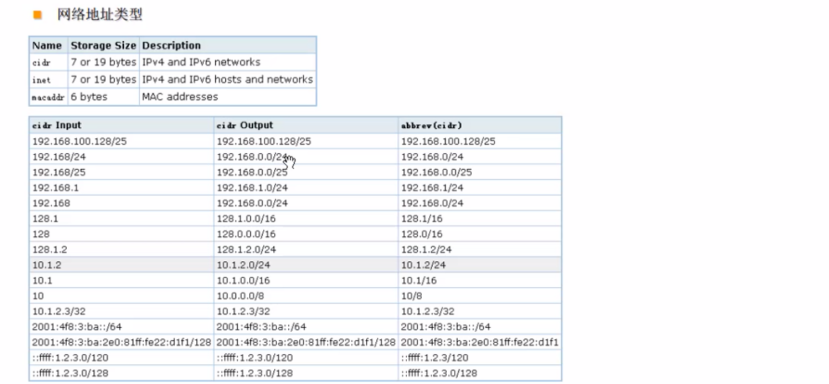
网段填充例子 :
Table "digoal.tbl_ ip_ info"
Column Typ
e
Modifiers
Id integer
Province character varying(10)
省份
start_ ip inet
开始IP
end_ ip inet
结束IP
digoal=> insert into tbl_ ip_ info values (1
,'
浙江
','192. 168. 1 .254','192.168.2.5');
digoal=> insert into tbl_ ip_ info values (2,
'
广东
' fK','192. 168.2.254','192.168.3.5');
digoal=> insert into tbl_ip_info values (3,'
湖南
','192.168.3.254','192.168.4.5');
digoal=> select id,generate_ serijes(0,end_ip-start_ip)+start_ ip from tbl_ ip_
info ;
产生多行
192. l68.1.254
192.168.1.255
192.168.2.0
192.168.2.1
192.168.2.2
192.168.2.3
192.168.2.4
192.168.2.5
192.168.2.254
192.168.2.255
10、比特类型,支持变长和定长
Bit strings are strings of l's and 0's. They can be used to store or visualize bit masks. There are two SQL bit types: bit(n) and bit varying(n), where n is a positive integer.
CREATE TABLE test (а BIT(3)
定长
,
b BIT VARYING(5));
变长
INSERT INTO test VALUES (B'101', B'00');
INSERT INTO test VALUES (B'10', B'101');
ERROR: bit string length 2 does not match type bit(3)
INSERT INTO test VALUES (B'10'::bit(3), B'101');
SELECT * FROM test;
A b
101 00
100 101 默认在末尾添加 0
11、全文检索类型
包含两个类型 , 比如一个字符串 , 存储在 tsvector, 搜索是否包含要的关键字 , 关键字相当于搜索的字符集 , 存在 tsvector 中 。
(1)tsvector
去除重复分词后按分词顺序存储
可以存储位置信息和权重信息
(2)tsquery
存储查询的分词,可存储权重信息
包含哪些字典 , 通过dictname标记逆行查询 。
全文检索类型要把字符串转换成分词 , 跟用到的字典有关系 ,$$ 类似于字符串外面引号的作用 , 转换成tsvector , 作为分词存储在tsvector , 分词支持位置信息 , 章节信息 , 总共分四个章节 , abcd , 章节在分词中是层次结构的意思 , 有主题 , 假如把a当作主题 , 检索a在主题里面 , 可以a: 1A, a出现在b中没关系 , 检索不到 , 方便可以在章节里面搜索 , 使用english字典拆分the fat rats , 在英语里面the基本搜不到 , 没有意义 , 不会放在分词中 ,
SELECT to_ tsvector (‘ postgraduate' )@@to_ tsquery(‘postgres:*’);
所有的顺序 , 所有的章节都比对出来 。postgraduate 当分词用 。 检索两个词转换成tsquery , 检索到fat , 检索到rat , 用 & 的符号扩起来 , 或者用或 , 只要匹配上fat或者匹配上rat | rat其中一个就是有效的tsquery , fat : ab , a章节和b章节匹配fat , 同时所有章节里面匹配到cat即可 ,SELECT to_ tsquery(’ postres:*‘): to_ tsquery
12、uuid类型
UUIDs could be generated by client applications or other libraries invoked through a server-side function.
specifically a group of 8 digits followed by three groups of 4 digits followed by a group of 12 digits, for a total of 32 digits
representing the 128 bits.
输出格式:
A0eebc99-9c0b-4ef8- Ъb6d-6ЪЬ9Ъd380all
五组
输入格式 :
AOEEBC99-9COB-4EF8-BB6D-6BB9BD380All
{aOeebc99-9c0b-4e f8 -bb6d-6bЬ9ЬdЗ80all}
aOeebc999cOb4e f8ЬЬб d6bb9bd380all
aOee-bc99-9cOb-4e f8- -ЬЬБd-БbЬ9- -bd38-0all
{aOe ebc99-9cOb4e f8-ЬЬб d6bb9-bd380all}
13、数组类型
(1)不限长度
目前PostgreSQL未对长度强限定,如int[]和int[10]都不会限定元素个数。 维度不做强限制 。 如果要写二维数组 , 后面所有的值必须要写二维数组 , 结构严 。
array_ length(ARRAY[[1,2,3,4,5],[6,7,8,9,10]],1) 二维数组
(2)不限维度
目前PostgreSQL未对维度强限定,如int[]和int[][],效果是一样的,都可以存储任意维度的数组。
(3)矩阵强制
多维数组中,同一个维度的元素个数必须相同, 比如一维里面每一个元素都是五个 , 不能出现四个六个七个 。
正确
array[[1,2,3,4],[5,6,7,8]]
不正确
array[[1,2,3,4],[5,6,7]] 前面存数字 , 后面不能存字符串 , 在同一维度里面不能不一样
(4)元素强制
元素类型必须一致
正确
array[1,2,3]
不正确
array[1,2,'abc]
(5)扩展
一维数组支持prepend, append,, cat操作
array_ append(ARRAY['digoal','francs' ],'david') 变成新的数组
array_prepend(david',ARRAY['digoal,'francs'])
二维数组仅支持cat操作, 二维数组不能做 prepend, append, 操作 , 只能再往里面添加数组 , 两个数组合并成新的数组
array_cat(ARRAY['digal",zhou'"f"francs,'tan']], ARRAY['david",guo])
<<digoal, zhou> ,<francs . tan> , <david , guo>>
(6) Subscript
指的是postresql的下标 ,元素脚本默认从1开始, 也可以指定。
array_ lower(ARRAY[[1,2,3,4,5],[6,7,8,9,10]], 2)
第二个维度的 lower 是 1, 第一个维度是 345, 第三个维度没有
array_ lower('[-3:-2]={1,2}::int[], 1)
制定下标的数组
select array_upper([-3:-2]={1,2}:int[], 1)
14、切片
array_ dims(ARRAY[[1,2,3,4,5],[6,7,8,9,10]])
       a[1:2][1:1]= {

       {1},{3}}
第一个[]中的1表示低位subscript, 2表示高位subscript值。
第二个[]中左边的1表示低位subscript,右边的l表示高位subscript值。
a[2:3][1:2]= { {3,4},{5,6}}
分片的另一种写法,只要其中的一个维度用了分片写法,其他的维度如果没有使用分片写法,默认视为高位。
如a[2:3][2]等同于a[2:3][1:2]
PostgreSQL ARRAY datatype introduce
具体可以参考网页中的恶用法 : h t tp://blog.163.com/digoal@126/blog/static/163877040201201275922529/
例1:
ARRAY[1.2,3.4]是 一 维数组。
ARRAY[1.2][3.4].[5,6]]是二维数组。
例2:
ARRAY[["digoal ,zhou'][a',b',c]]是错误的,因为第二个维度中的第一个array有2个元素,而第二个array有3个元素不是一个矩阵,个数必须 一 致,同时类型也必须一致。
例3:
ARRAY["'digoal, :zhou'][1 ,2]]是错误的,因为[digoal' ,zhou]是te>t0类型,而[1 .2]是int]类型。
例3:
ARRAY[['digoal' ,zhou'][,1 ,2]] 是错误的。因为[digoal' ,zhou']是text[]类型,而[1 .2]是int[]类型。
元素
一 维数组ARRAY[1,2,3.4]中的4个元素分别是1.2.3, 4.这些in型的值。
二维数组ARA[[1.2][3.4].[5,6]]中的第 一 维度有3个元素是ARRAY[1.2], ARRAY[3.4] , ARRAY[5.,6]这些int[]类型的值,第二个维度的第一个subscript的元素有两个, 分别是1.2,第二个subscript 分别是3.4,第三个subscript分别是5,6,元素之间的分隔符,除了box类型是分号,其他类型的分隔符都是逗号。
扩展性
一
维数组可以扩展,二维数组无法扩展,参考htp:/lo/ 163
.com/digoal@126/blog/static/163877040201201272718196/
subscript 下标
访问ARRAY中的元素需要提供subscript值,默认是从1开始编号,除非赋值的时候强制指定subscript。
ARRAY[[1,2], [3, 4],[5,6]] as a
a[1][1] = 1;
a[1][2] = 2:
a[2][1] = 3;
a[2][2] = 4:
a[3][1] = 5;
a[3][2] = 6;
第一个元素是a 11, 第二个元素是a 12,1 和 1 是下标 , 表示第一个维度的第几个值 , 第二个维度是第几个值 , 第一个维度的值是 1,2, 放到第二个维度里面是 1,2 里面的第一个值 , 所以出来的是 1, 对于 1 和 2, 第一个 1 指的还是 1,2 元素 , 第二个维度里面取的是第二个元素 2。
array_ dims, 返回的是各个维度中的低位subscrip和高位subscript。 第一个方框指的是第一个维度 , 第一位是 1, 第一个维度里面的第一个元素的下标是 1, 最大的元素的下标是 2,[1:2][1:5], 对于第二个维度的下标 , 最小的下标是 1, 最大是 5, 总共是 5。
array_ length, 返回的是array中指定维度的长度或元素个数。
digoal=> select array. length (ARRAY[[I2,3 4.5],[6.7.8.9 10]], 1);
Array_lenath
2
digoal=> select array, length (ARRAY[[1,2,3, 4,5],[6, 7,8,9, 10]], 2);
Array_ Length
5
第一个维度的长度是 2, 五个元素 , 第二个维度有五个元素 , 返回的是 5。
array_ lower, 返回的是ARRAY中指定维度的低位subscript值 。
digoal=> select array
_
lower (ARRAY[(1,2,3, 4,5], [6,7,8,9,10]], 2);
array_ lower
array_ lower指的是第一个下标 , 第二个维度第一个下标是 1。
digoal=> select array_ lower(' [-3;-2]=[1,2]'::int[],1);
Array_lower
第一个维度的下标是 -3, 最低位是 -3, 没有第二个维度 , 因为是一维数组 。
array_ upper, 返回的是ARRAY中指定维度的高位subscript值,如下
digoal=> select array_ upper(ARRAY([1,2,3, 4,5],[6,7,8,9,10]], 2);
Array_upper
5
上标是指维度里面最大的元素的标记位 , 比如在二维里面最大的是 5, 在一维里面只有两个元素 , 最大是 2。
下面就是强制指定subscript值。
digoal=> select array, _upper(' [-3:-2]=[1,2]' :int[], 1);
Array_ upper
-2
上标是 -2, 因为指定了下标 , 用方框指定下标 。 比如改成多维数组 , 假设第二个维度是一个元素 , 第一个维度的下标是 -2, 第二个维度返回的是 1。
array_ prepend,
用于在一维数组的前面插入元素,如下
digoal=> select array, prepend' digoal', ARRAY[' francs' ,' david' ]);
Array_prepend
array_ cat,
用于两个相同维度的数组的连接,或者
一
个n维数组和一个n+ 1维数组的连接,如下:
digoal=> select array_ cat (ARRAY[' francs' ], ARRAY[ di eoal' .' david 1]):
array, cat
[francs, digoal, david)
digoal=> select array_ cat (ARRAY[' francs' ], ARRAY[[' di goal' ]]):
Array_ cat
[[francs], [digoal]]
generate_ subscripts
, 用于按顺序返回ARRAY的指定维度的subscript(s)值。
正向返回第一维度的subscript值。
digoal=> select generate_subseripts(a,1) from (select ARRAI['d','b','c''d']as a) t;
generate_ subscripts
把一维数组截出来 , 一维的下标截出来 。
多维数组指定下标 , 第二个维度有三个元素 , 三个元素的上标下标 , 把a数组的第二个维度 , 下标是 2,3,4。
digoal=> select generate_subseripts(a,2)from(select '[-5:-4][2:4
]
=
[[
1,2,3], [4,5, 611' ::int[] as a) t;
generate_ subscripts
14、 自定义类型
create type test as (info text,id int,crt_ time timestamp(0));
创建表时默认创建一个同名复合数据类型composite type,因此表名和自定义类名不能重复 , 先创建类型再创建表不可以 , 先创建表再创建类型也不可以 , 会报同样的错 。
create table test (id int primary key ,info text);
ERROR: relation "test" already exists
举例
CREATE TYPE inventory_ item AS (创建数据类型 , 复合数据类型包含三个字段
Name
text,
supplier_ id
integer,
Price
numeric
);
CREATE TABLE on_ hand
(使用数据类型
Item
inventory item,
Count
integer
);
INSERT INTO on_hand VALUES (ROW(fuzzy dice', 42, 1.99), 1000);
SELECT (on_ hand.item).name FROM on_ hand WHERE (on_ hand.item).price <10;
name
fuzzy dice
SET和INTO子句自定义类型不能加括号引用,其他子句中的自定义类型可以加括号引用 , 编辑复合类型的值可以用 ROW(fuzzy dice',10, 100) 方式
UPDATE on_ hand SET item = ROW(fuzzy dice',10, 100) WHERE count= 1000;
更新复合类型某一个字段的值可以通过item.price , 在where条件里面可以通过加下标 , 加表名 , 字段名 , 用法有一定的区别 。
UPDATE on_ hand SET item.price = (on_hand.item).price + 100 WHERE
(on_hand.item).name= *'fuzzy dice';
直接通过字段名和字段类型里面的指定的名字进行引用 。
INSERT INTO on_ hand (item.name, item.supplier_ id) VALUES(test, 2.2);
Postgres
=
# select * from on_ hand;
Item
count
("fuzzy dice'",10,200) 1000
(test,2,)
oid (object identifier) 4 bytes
xid (transaction identifier) 4 bytes xmin,xmax
cid (command identifier) 4 bytes cmin,cmax
tid (tuple identifier) 6 bytes ctid
以下为各系统表对应的oid列的alias,类型都是oid
可使用 Hnamespace, 或者默认的search_ path先后顺序检索
|
Name |
References |
Description |
Value Example |
|
oid |
any |
numeric object identifier |
564182 |
|
regpr oc |
PE_proc |
function name |
sum |
|
regprocedure |
PE_proc |
function with argument types |
sun (int4) |
|
regoper |
pE_operator |
operator name |
+ |
|
regoperator |
PE_operator |
operator with argument types |
* (integer, integer) or - QRONE, integer) |
|
rerclass |
Pe_class |
relation name |
Pg_type |
|
regtype |
PZ_type |
data type name |
integer |
|
regconfig |
Pg_ ts_ config |
text search configuration |
english |
|
regdictionary |
Pe_ts_ dict |
text search dictionary |
simple |
test=# create sequence seq_ test start with
1
;
CREATE SEQUENCE
test= # select 'seq_ test'::regclass;
regclass
seq_ test
test= =# select 'seq_ test'::regelass::oid;
oid
49247
test= =# select 'sum(int4)'::regprocedure;
regprocedure
sum( integer)
test= # select 'sum(int4)'::regprocedure::oid;
Oid
2108
把sum函数转换成regprocedure类型 , 站换成regprocedure
sum( integer)对应的函数是什么 , 跟object id是通用的类型 。
15、 Pseudo-Types 伪类型
|
Name |
Description |
|
any 代表任何类型 , 创建函数非常有用 , 函数可以接收任何数据类型 , 指定any |
Indicates that a function accepts any input data type. |
|
anyarray 代表任何数组类型 |
Indicates that a function accepts any array data type (see Section 35.2.5). |
|
anyelement |
Indicates that a function accepts any data type (see Section 35.25). |
|
anyenum |
Indicates that a function accepts any enum data type (see Section 35.2,5 and Section 8.7). |
|
anynonarray |
Indicates that a function accepts any non-array data type (see Section 35.25). |
|
cstring |
Indicates that a function accepts or returns a null-terminated C string. |
|
internal |
Indicates that a function accepts or returns a server-internal data type. |
|
L anguage_handler |
A procedural language call handler is declared to return language_ handler. |
|
fdw_ handler |
A foreign-data wrapper handler is declared to return fdw_ handler . |
|
record |
Identifies a function returning an unspecified row type. |
|
triger |
A trigger function is declared to return trigger. |
|
void |
Indicates that a function returns no value. |
|
Opaque |
An obsolete type name that formerly served all the above purposes. |
推荐文章